A sentence is not a bag of words. The word not in the fifth position can cancel the verb in the eighth. Something has to carry the fifth word forward. A recurrent neural network is a person with one sticky note: it eats one token at a time, rewrites the note, and the note is the entire memory of what has been said so far.
The previous note in this series had a neighborhood. Sequences have an order. The prejudice changes: the same function, applied at every time, with the last note as an extra input.
If you have matrix–vector products and the chain rule, you are the intended reader. Every term is defined when it appears. We will run a one-unit network for three steps by hand, train it on the word hello, watch a gradient fall off a log plot, and repair the fall with a valve. A later note in this blog, Recurrent Memory and LSTMs, does the same algebra at more leisure.
- The sticky note
- Three steps, one unit
- A character-level language model
- Sampling
- Unrolling
- Backpropagation through time
- Why $\tanh$ cannot remember
- Vanishing and exploding
- LSTM: a valve, not a multiply
- Bidirectional, and a door
- A vanilla example in Python
The sticky note
Fix a sequence $x_1, x_2, \ldots, x_T$, each $x_t$ a vector. (A character, a word, a frame: one-hot, or an embedding. The algebra does not care.) A vanilla RNN keeps a hidden state $h_t$ of some fixed length $H$ and updates it by the same function at every time:
\[h_t \;=\; \tanh\bigl(W_{xh}\, x_t + W_{hh}\, h_{t-1} + b_h\bigr), \qquad h_0 = 0.\]The matrices $W_{xh}$ and $W_{hh}$ and the bias $b_h$ are shared: the same numbers at $t=1$ and at $t=400$. That is the recurrence. The network does not grow new weights for a longer sentence. The sticky note has a fixed number of squares.
From $h_t$ you may read an output,
\[\hat y_t \;=\; \mathrm{softmax}\bigl(W_{hy}\, h_t + b_y\bigr),\]a probability vector over whatever vocabulary you are predicting. Language modelling is the special case $\hat y_t \approx x_{t+1}$: at each step, guess the next token.
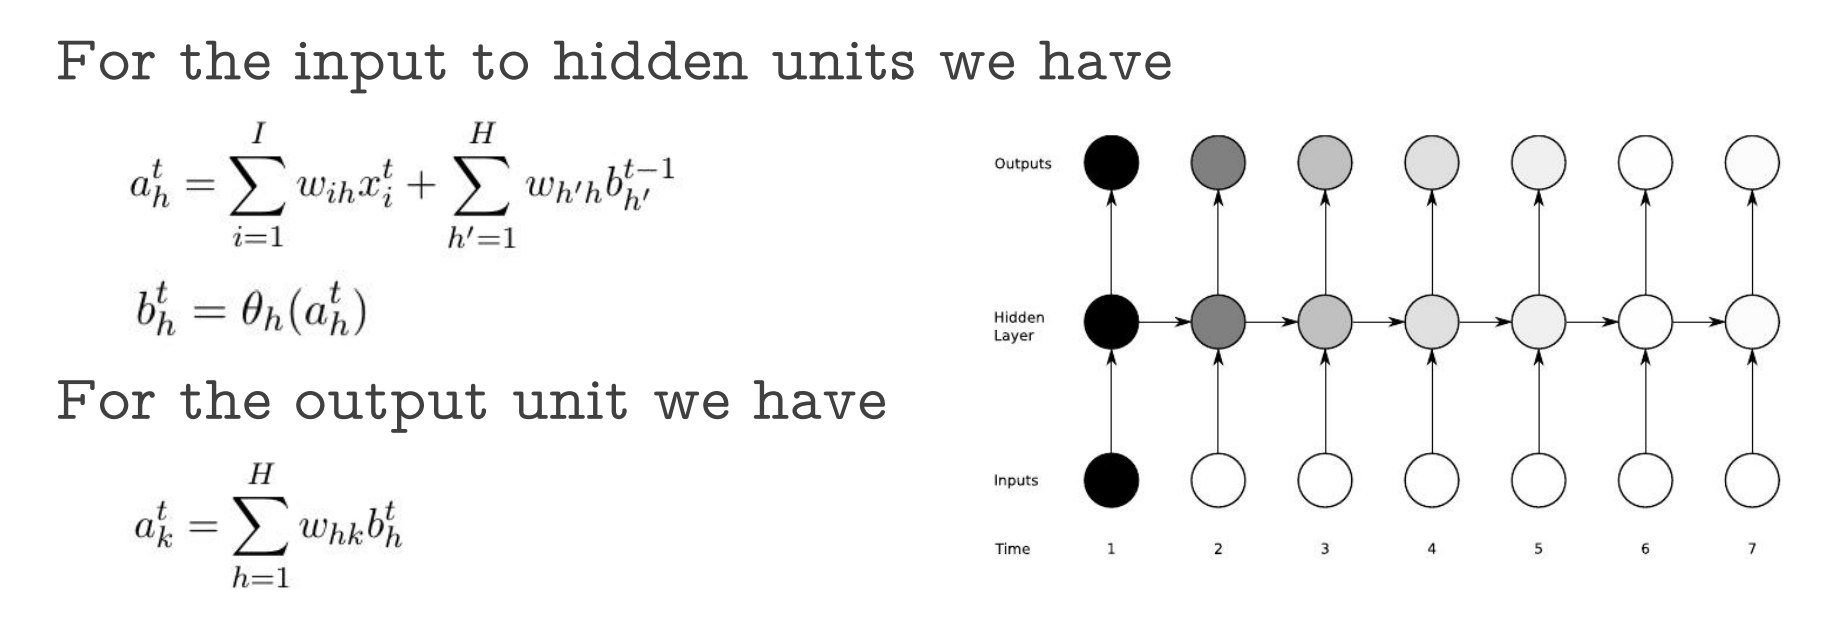
The figure writes the same thing in coordinates. $a_h^t$ is the pre-activation of hidden unit $h$ at time $t$; $b_h^t = \theta_h(a_h^t)$ is the activated hidden state (our $h_t$); $a_k^t$ is the output unit. The picture on the right is the same network drawn once per time step, with the hidden-to-hidden copy travelling along the row.
Two applications, before any more algebra.
- Sequence in, label out. Sentiment, topic, “does this protein bind.” You run the recurrence to the end and classify $h_T$.
- Sequence in, sequence out. Translation, tagging, language modelling. You read $\hat y_t$ at every $t$, or you encode the whole input into $h_T$ and then decode a new sequence from it.
Three steps, one unit
Hide every matrix. One hidden unit, no bias, $w_x = 1$, $w_h = 0.5$, and a three-step input $x = (1,\, 0,\, 1)$. Then $h_t = \tanh(x_t + 0.5\, h_{t-1})$, starting from $h_0 = 0$.
\[\begin{aligned} h_1 &= \tanh(1 + 0.5\cdot 0) &&= \tanh(1) &&\approx 0.762,\\ h_2 &= \tanh(0 + 0.5\cdot 0.762) &&= \tanh(0.381) &&\approx 0.364,\\ h_3 &= \tanh(1 + 0.5\cdot 0.364) &&= \tanh(1.182) &&\approx 0.828. \end{aligned}\]The $0$ in the middle did not wipe the note. It faded it: $0.762$ became $0.364$, and the third $1$ wrote on top of what remained. That is memory, of a sort. It is also the whole problem. Each step multiplies the past by $0.5$ and then squishes through $\tanh$. Ten steps of silence and the first $1$ is gone.
Keep these three numbers. The rest of the note is “what if we do not multiply the past by $0.5$.”
A character-level language model
The smallest interesting vocabulary is four letters, ${h,e,l,o}$ — enough to spell hello. Each character is a one-hot vector of length $4$:
Feed h, then e, then l, then l. At each step the hidden state is a small vector, say of length $3$, and
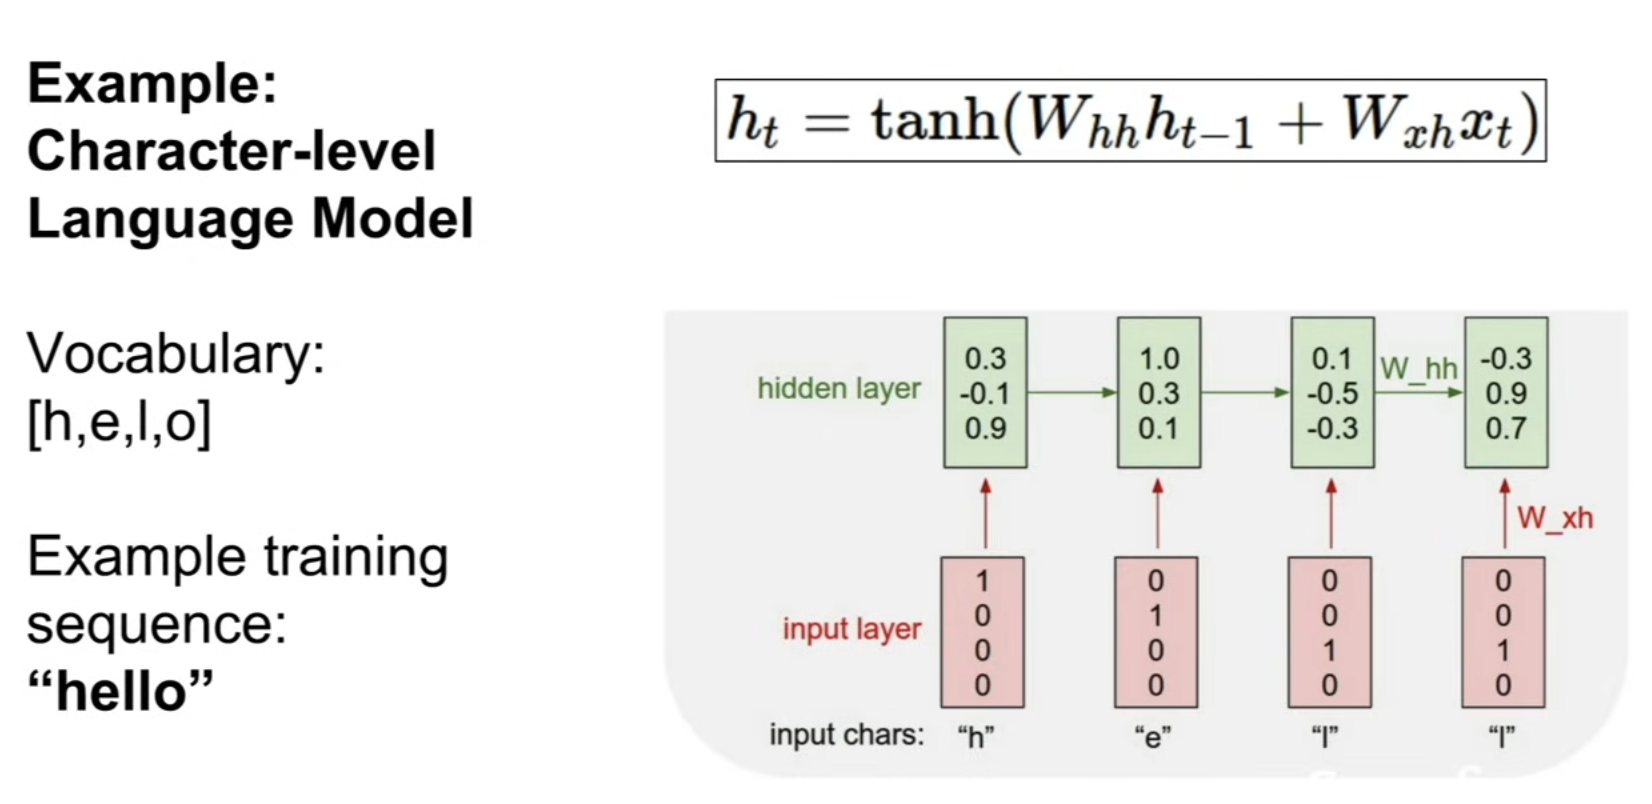
The numbers in the green boxes are made-up but typical: after h the state is something like $(0.3,\,-0.1,\,0.9)$; after e it has been rotated and squashed to $(1.0,\,0.3,\,0.1)$; and so on. The same $W_{xh}$ and $W_{hh}$ act at every arrow. The network is not “looking at hello.” It is looking at one letter, plus a three-dimensional sticky note.
To train, you also want a guess at the next letter. That is a length-$4$ vector of scores, $W_{hy} h_t$, one score per vocabulary item.
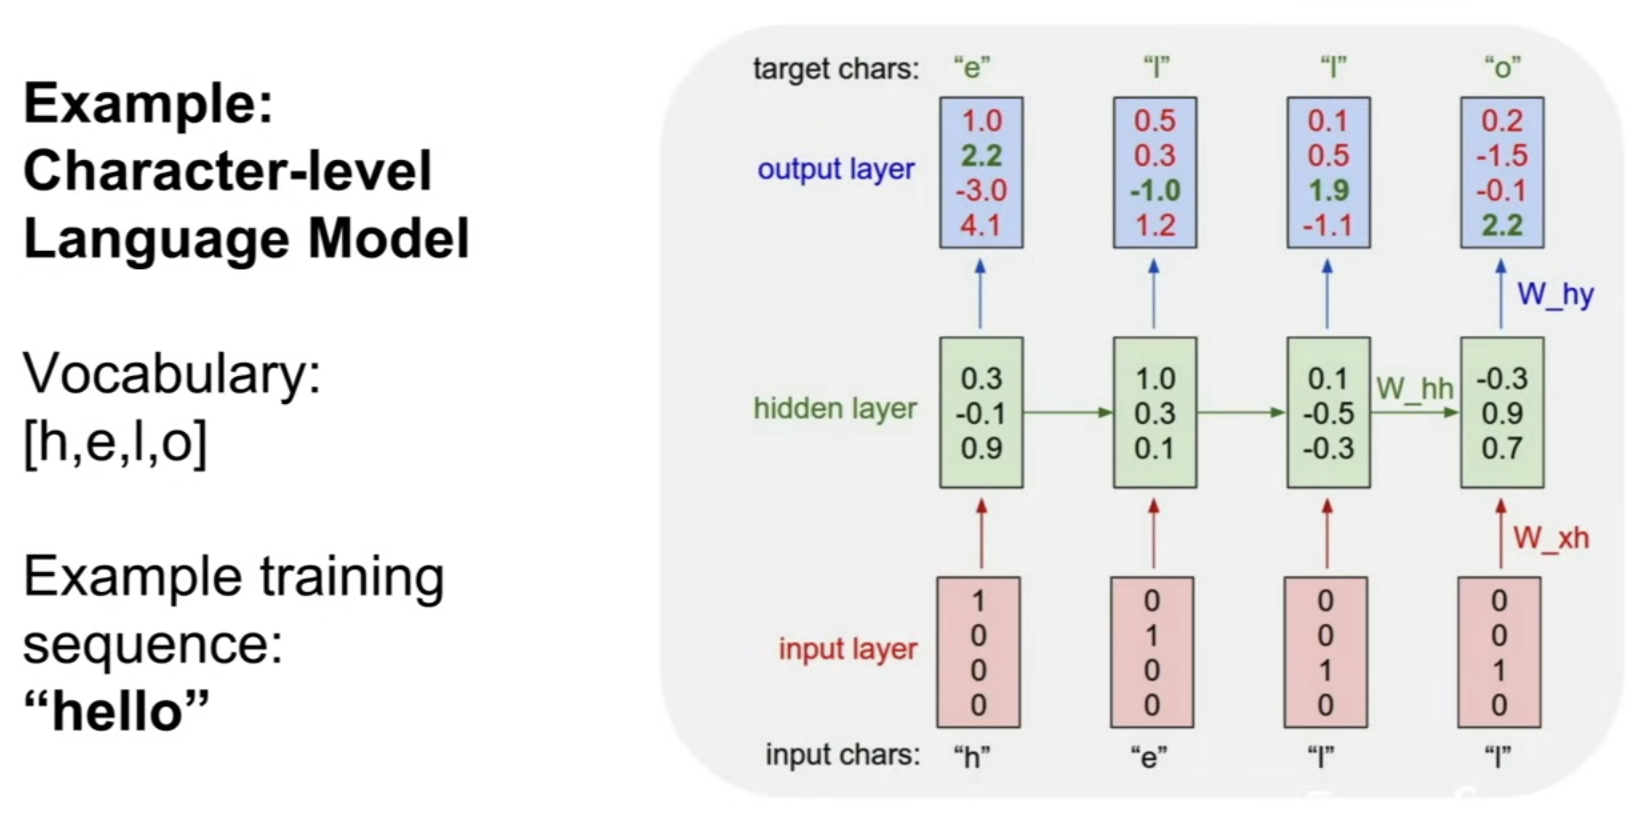
At the first step the input is h and the target is e. At the second, input e, target l. Then l$\to$l, then l$\to$o. The loss is the cross-entropy between the softmax of those blue scores and the one-hot target. Four tiny classification problems, tied together by $W_{hh}$.
Sampling
At test time there is no target. You start with a seed — say h — run one step, and sample a character from the softmax. Then you feed that character back in as the next $x_t$. The network writes by talking to itself.
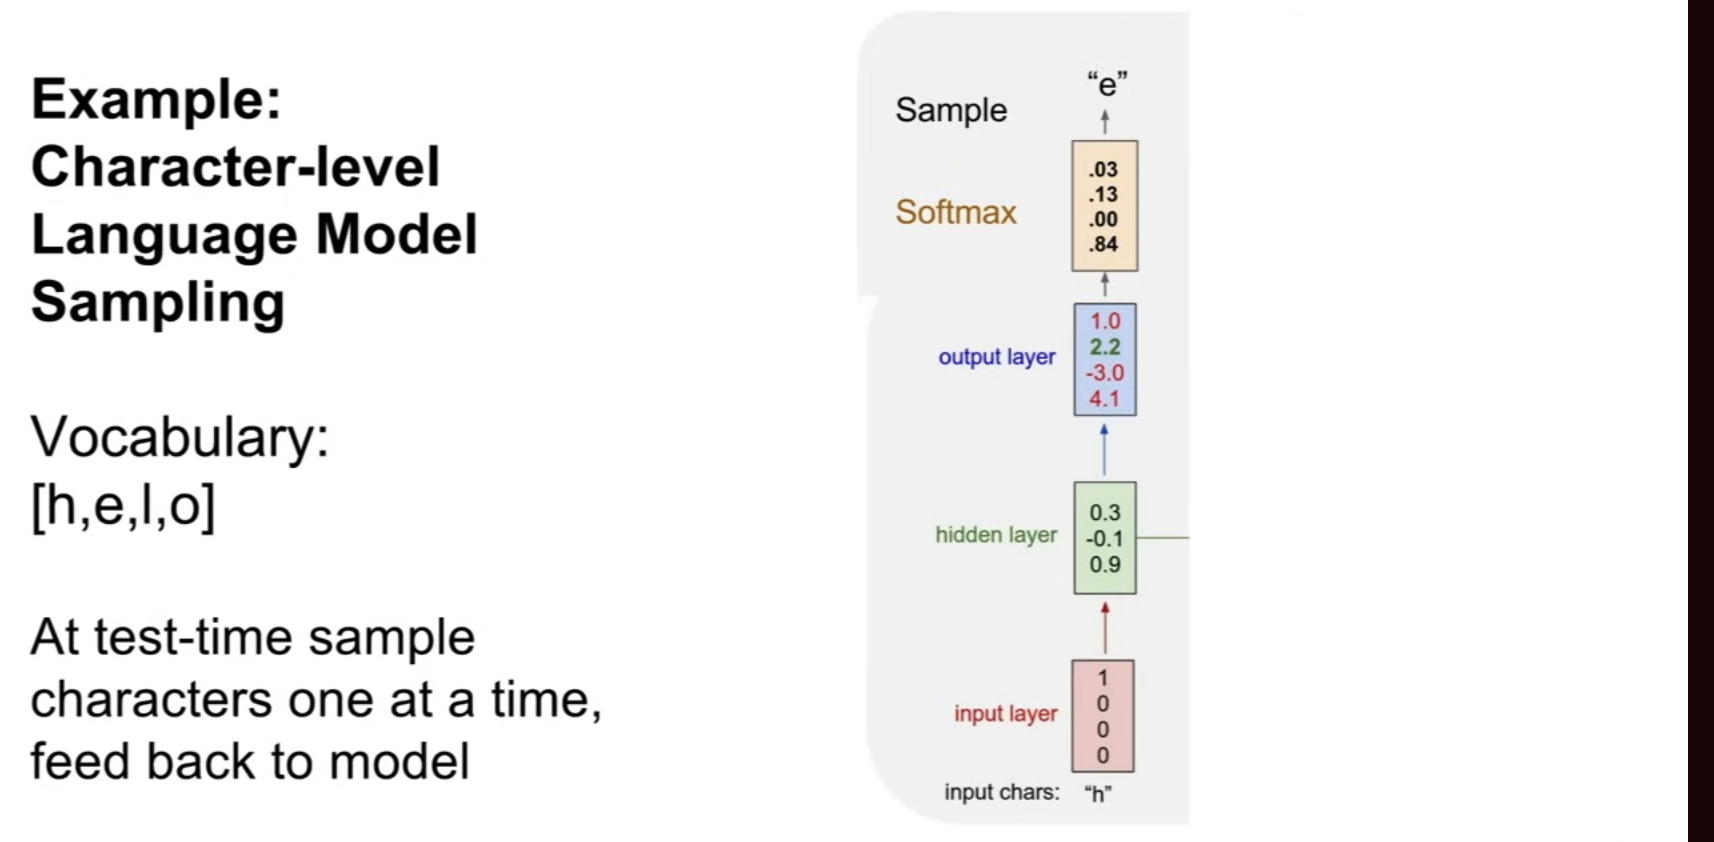
In the figure the scores $(1.0,\, 2.2,\, -3.0,\, 4.1)$ become probabilities $(0.03,\, 0.13,\, 0.00,\, 0.84)$ after softmax. The mass is on o. The arrow draws e anyway. Treat it as a sample, not as $\mathrm{argmax}$. (A network that always took the max would emit ooooooo and call it a day. Sampling is how a language model has a temperature.) Continue until you emit a stop token, or until you are tired of the paragraph.
This is already a language model. Karpathy’s Unreasonable Effectiveness of Recurrent Neural Networks is this loop, trained on Shakespeare, Linux source, and Wikipedia markup, and it is still the right first experiment. The Linux model closes its own parentheses. The Shakespeare model almost scans. Neither understands. Both have a sticky note.
Unrolling
The compact picture of an RNN is a loop: $h$ feeds back into itself. The honest picture is that loop unrolled for $T$ steps.
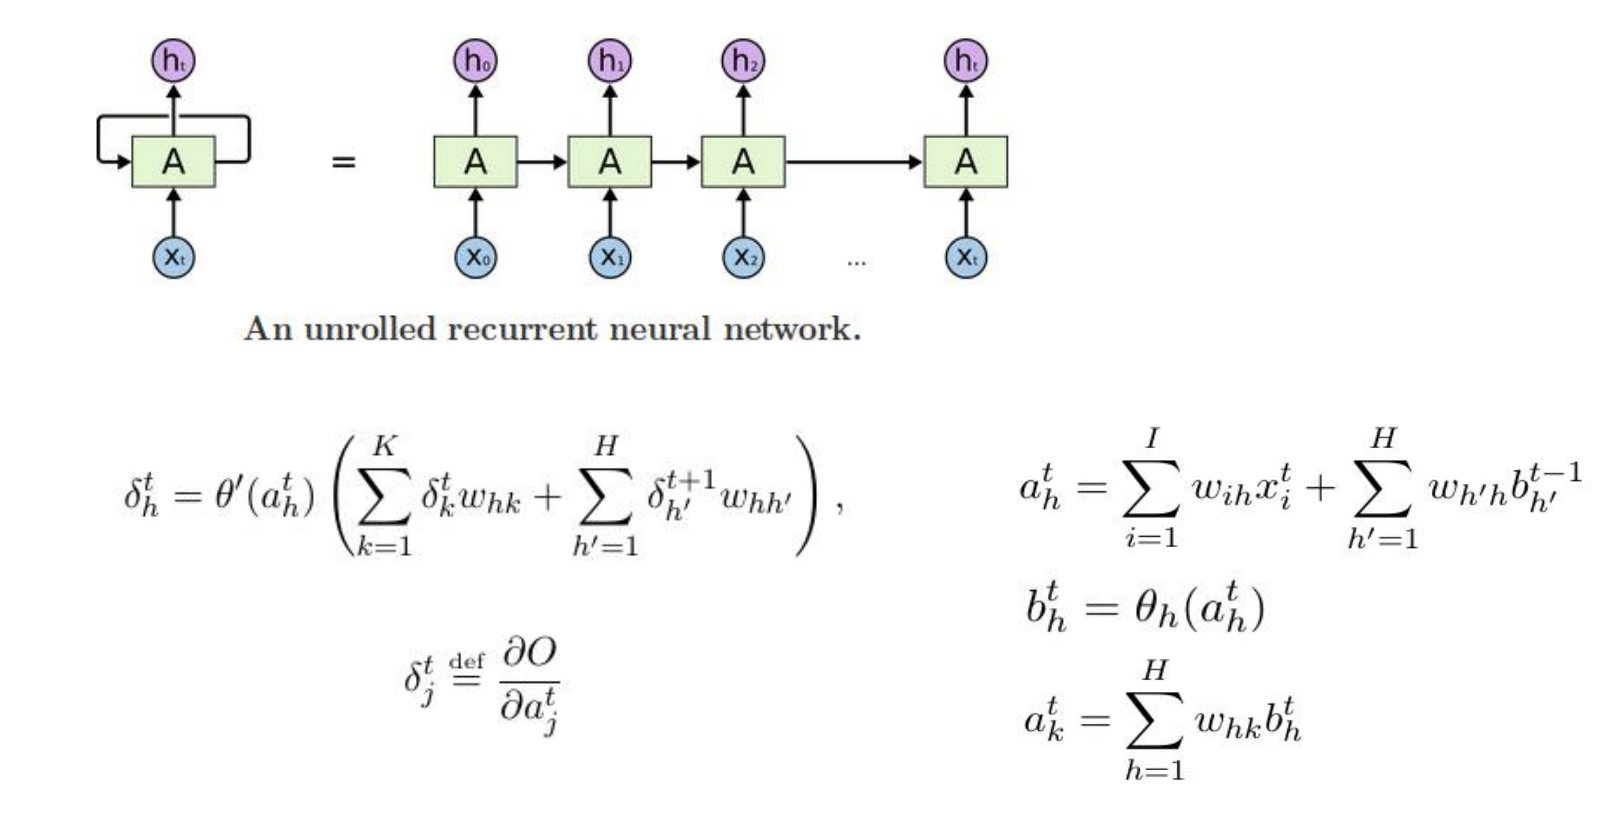
The block $A$ is the pair of equations above. It is the same block. Training will use the chain rule on this long chain, which is why the figure also writes the backward recurrence for the hidden error $\delta_h^t$. A sequence of length $T$ is a feedforward network of depth $T$ with the additional constraint that the $T$ copies of $W_{hh}$ are equal. Depth you do not get to choose: it is the length of the sentence.
Backpropagation through time
Training is gradient descent on the total loss $\mathcal{L} = \sum_t \ell(\hat y_t,\, y_t)$. The parameters sit inside every copy of the block, so the chain rule has to run backward along the unrolled chain. That is backpropagation through time (BPTT).
Write $z_t = W_{xh} x_t + W_{hh} h_{t-1} + b_h$, so $h_t = \tanh(z_t)$. The hidden state at $t$ affects the loss at $t$ and every later loss, through $h_{t+1}, h_{t+2}, \ldots$. The gradient that reaches $h_k$ from a loss at time $T$ is a product of Jacobians:
\[\frac{\partial \mathcal{L}_T}{\partial h_k} \;=\; \frac{\partial \mathcal{L}_T}{\partial h_T} \prod_{j=k+1}^{T} \frac{\partial h_j}{\partial h_{j-1}}, \qquad \frac{\partial h_j}{\partial h_{j-1}} = \mathrm{diag}\bigl(\tanh'(z_j)\bigr)\, W_{hh}.\]Each factor contains $W_{hh}$. Over a long stretch you are taking a high power of (a diagonal of numbers in $(0,1]$, times $W_{hh}$).
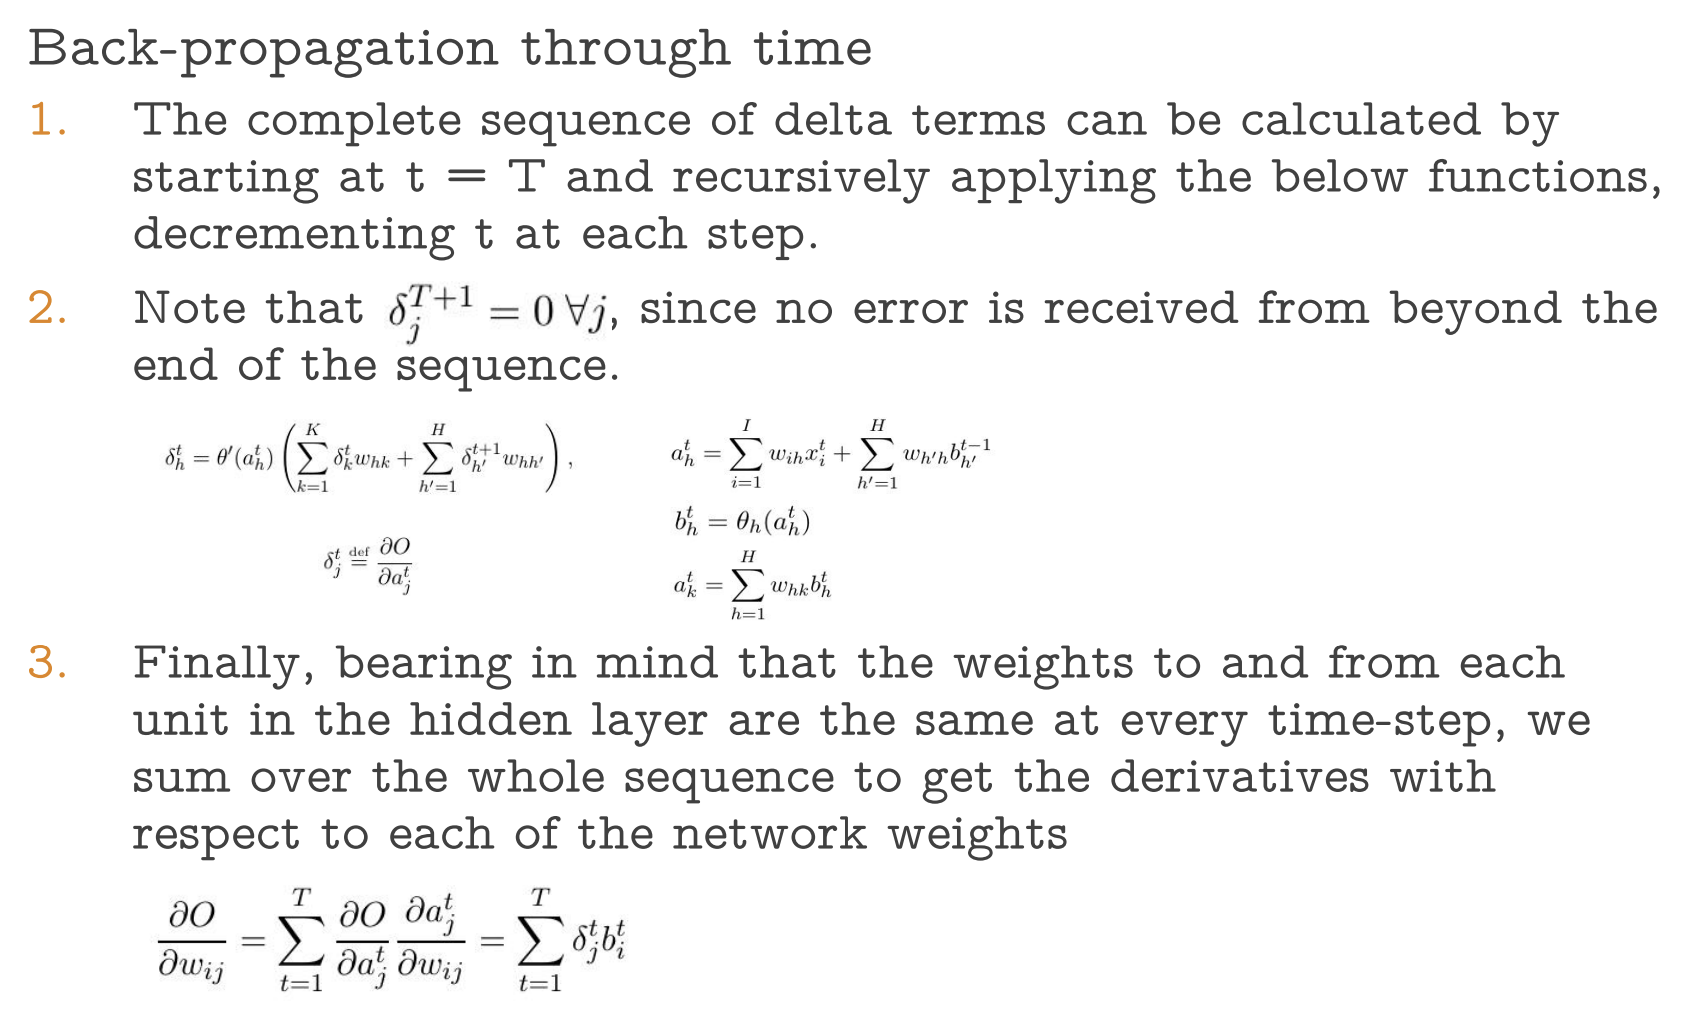
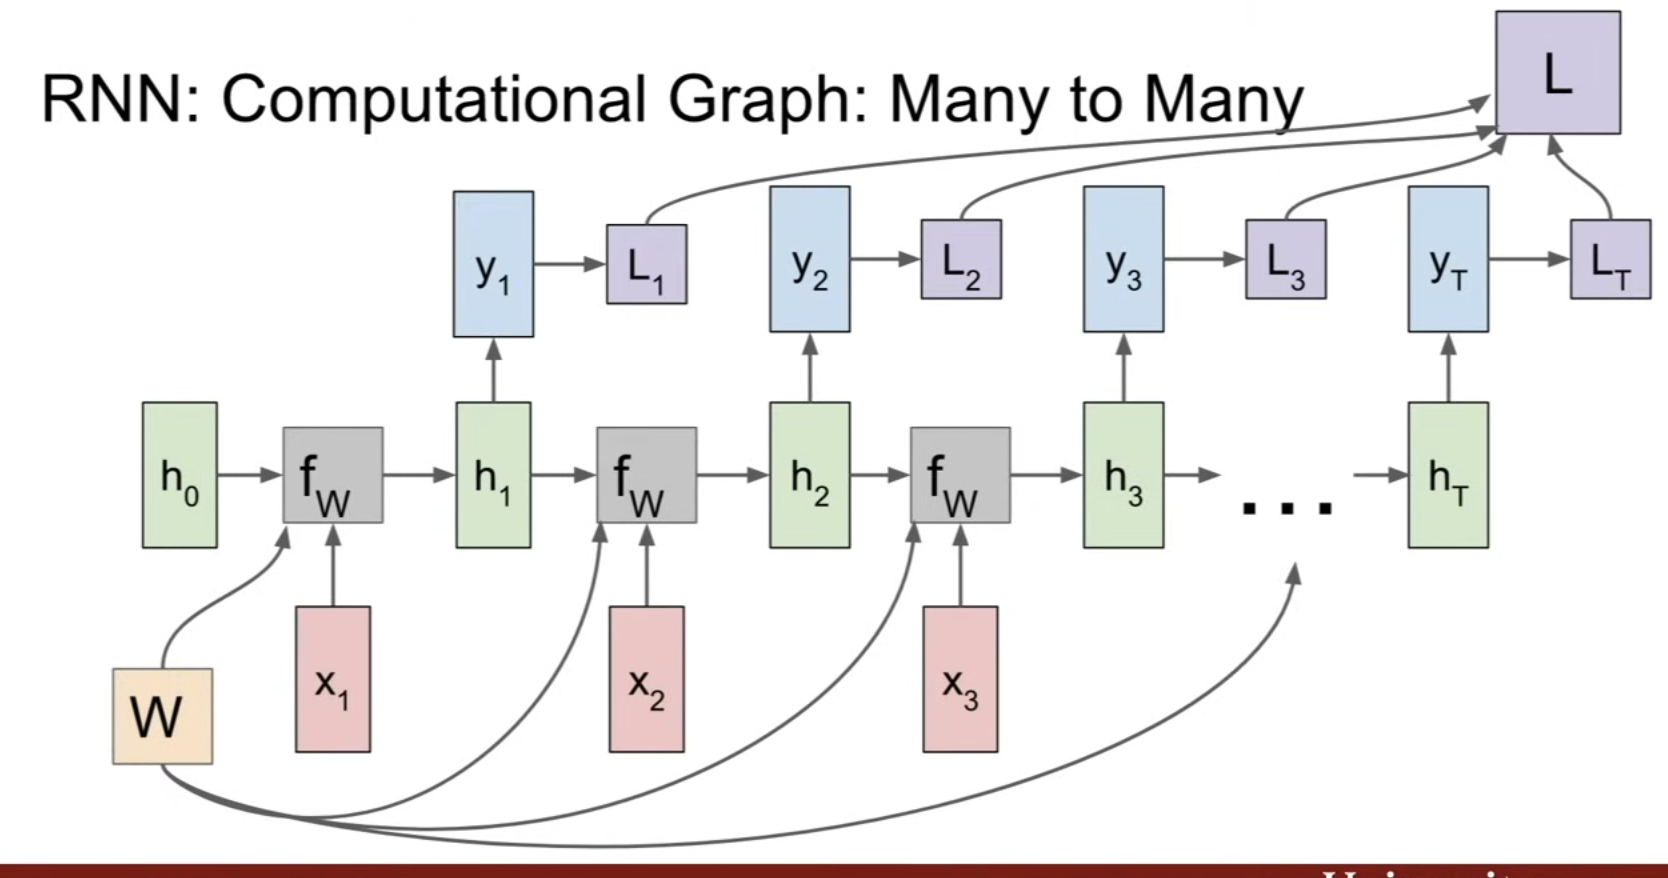
That is all BPTT is: ordinary backprop on the unrolled graph, with the copies of $W_{hh}$ identified so their gradients add. Truncated BPTT is the same thing with a short memory: you pretend the sentence started $K$ steps ago, so the product has at most $K$ factors. Cheap. Also an admission that the product was never going to survive the whole paragraph.
Why $\tanh$ cannot remember
The derivative of $\tanh$ is $1-\tanh^2 z$. It is at most $1$, at the origin, and it is near $0$ once $\lvert z\rvert$ is a few units. Saturated units do not pass gradient. Unsaturated units pass at most a factor of $1$, and typically less.
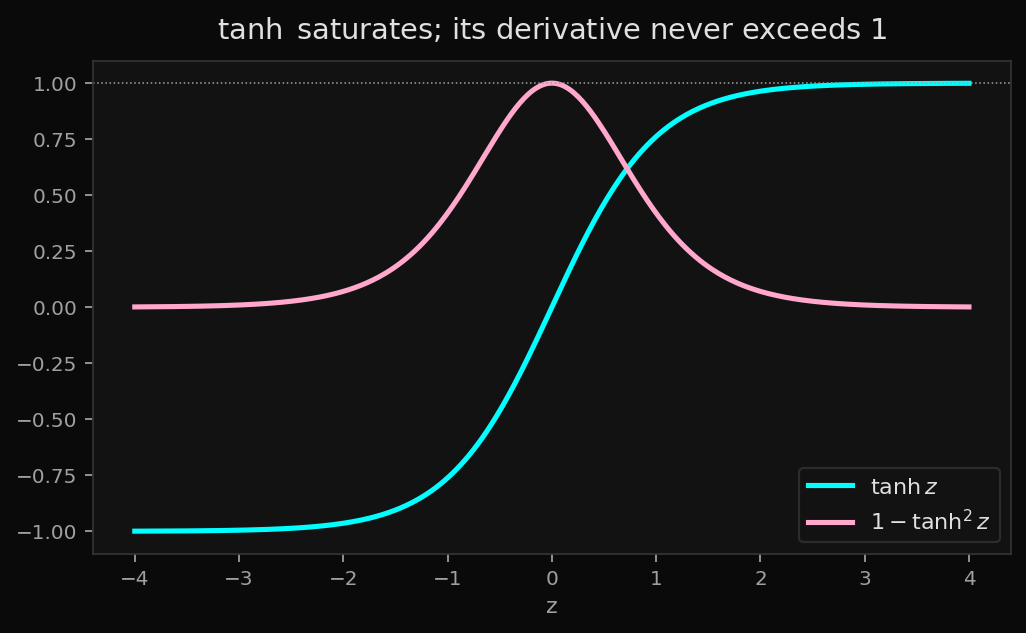
Sigmoid is worse: $\sigma’(z)=\sigma(z)(1-\sigma(z))$ is at most $1/4$. A deep feedforward net with sigmoids has the same disease. Recurrence makes the depth equal the length of the sequence. You can pick the number of layers of a CNN. You cannot pick the number of words in a sentence you have not read yet.
Vanishing and exploding
Look at that product again. Let $\sigma_{\max}$ be the largest singular value of $W_{hh}$, and pretend $\tanh’\approx 0.5$ on average, $W_{hh}$ of size about $0.9$.
| \(t\) | vanilla \((0.5\times 0.9)^t\) | LSTM \(f=0.9\), \(0.9^t\) | LSTM \(f=1\) |
|---|---|---|---|
| 0 | 1 | 1 | 1 |
| 5 | \(1.8\times 10^{-2}\) | 0.59 | 1 |
| 10 | \(3.4\times 10^{-4}\) | 0.35 | 1 |
| 20 | \(1.2\times 10^{-7}\) | 0.12 | 1 |
| 40 | \(1.3\times 10^{-14}\) | 0.015 | 1 |
At step $20$ the vanilla signal is $10^{-7}$. The loss at the end of the sentence cannot reach the first words. The network cannot learn “the subject was plural, so the verb should be.” This is vanishing gradients.
If instead $\sigma_{\max}>1$, the product grows exponentially. Updates become nonsense; parameters jump off the page. This is exploding gradients. The cheap repair is to clip: if the gradient vector is longer than some $C$, rescale it to length $C$. Clipping saves you from explosions. It does not restore a vanished signal. You cannot clip a zero back to life.
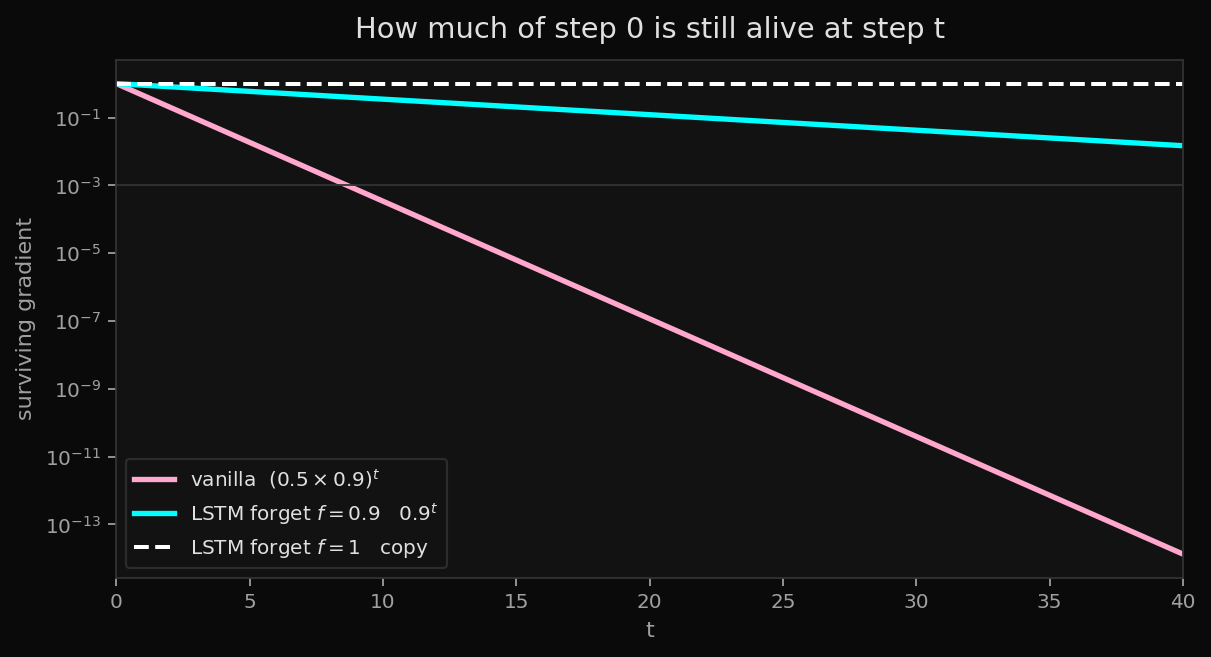
The diagnosis is due to Hochreiter (1991) and to Bengio, Simard, and Frasconi (1994). The repair that stuck is to stop multiplying into the memory.
LSTM: a valve, not a multiply
A long short-term memory cell, Hochreiter and Schmidhuber 1997, keeps a second vector $c_t$, the cell state, which is updated additively. Gradients that travel along $c$ are not forced through a $\tanh$ and a $W_{hh}$ at every step. They can, if the gates so choose, just copy.
The cell has three gates — vectors of numbers in $(0,1)$, produced by a sigmoid $\sigma$ — and one candidate update, produced by a $\tanh$. Concatenate the previous hidden state and the current input, write $[h_{t-1},\, x_t]$, and:
\[\begin{aligned} f_t &= \sigma\bigl(W_f [h_{t-1},\, x_t] + b_f\bigr) && \text{forget: what to erase from } c_{t-1}, \\ i_t &= \sigma\bigl(W_i [h_{t-1},\, x_t] + b_i\bigr) && \text{input: what to write into } c, \\ g_t &= \tanh\bigl(W_g [h_{t-1},\, x_t] + b_g\bigr) && \text{candidate: the proposed new contents}, \\ o_t &= \sigma\bigl(W_o [h_{t-1},\, x_t] + b_o\bigr) && \text{output: what to reveal as } h_t. \end{aligned}\]Then the two state updates:
\[c_t \;=\; f_t \odot c_{t-1} \;+\; i_t \odot g_t, \qquad h_t \;=\; o_t \odot \tanh(c_t).\]The symbol $\odot$ is the Hadamard (entrywise) product. Each coordinate of $c$ has its own forget valve and its own write valve.
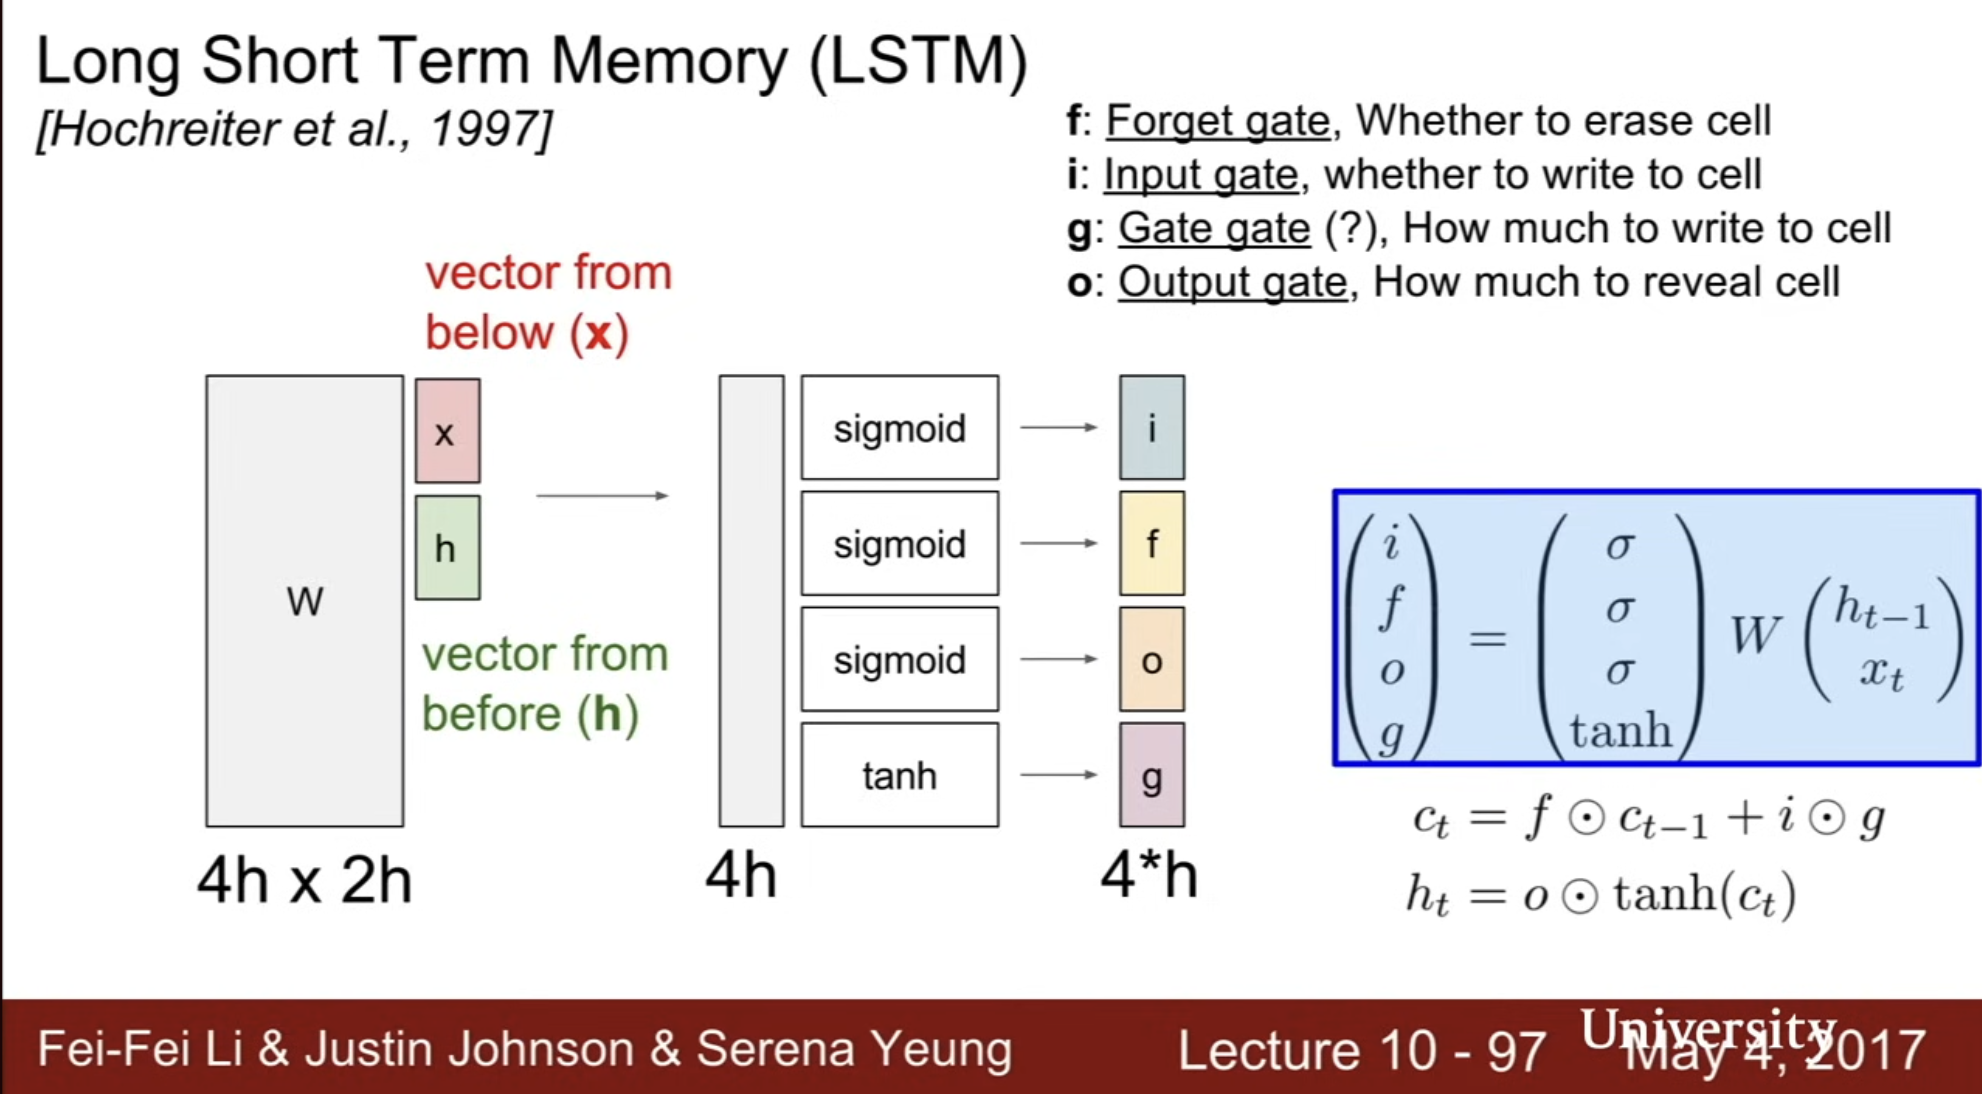
Read the slide. One matrix $W$ of shape $4H \times (H + \dim x)$ produces the four pre-activations at once; three go through $\sigma$, one through $\tanh$. The line that matters is $c_t = f \odot c_{t-1} + i \odot g$. If $f \approx 1$ and $i \approx 0$, the cell copies. If $f \approx 0$ and $i \approx 1$, the cell overwrites. The gradient $\partial c_t / \partial c_{t-1}$ is a diagonal of $f_t$’s, not a product of $W_{hh}$’s. That is the highway in the figure above.
A practical trick, because it is free and it works: initialize $b_f$ to $1$ (or $2$). Then at the start of training $f\approx \sigma(1)\approx 0.73$, and the cell is already more copy than erase. Jozefowicz, Zaremba, and Sutskever (2015) found this by accident and then on purpose. The cell wants to remember; you have to let it.
The same equations, in the older Graves notation ($b$ for activations, $s$ for the cell, $\phi,\iota,\omega$ for forget/input/output), are the figure below. It is the same cell. The letters moved; the valve did not.
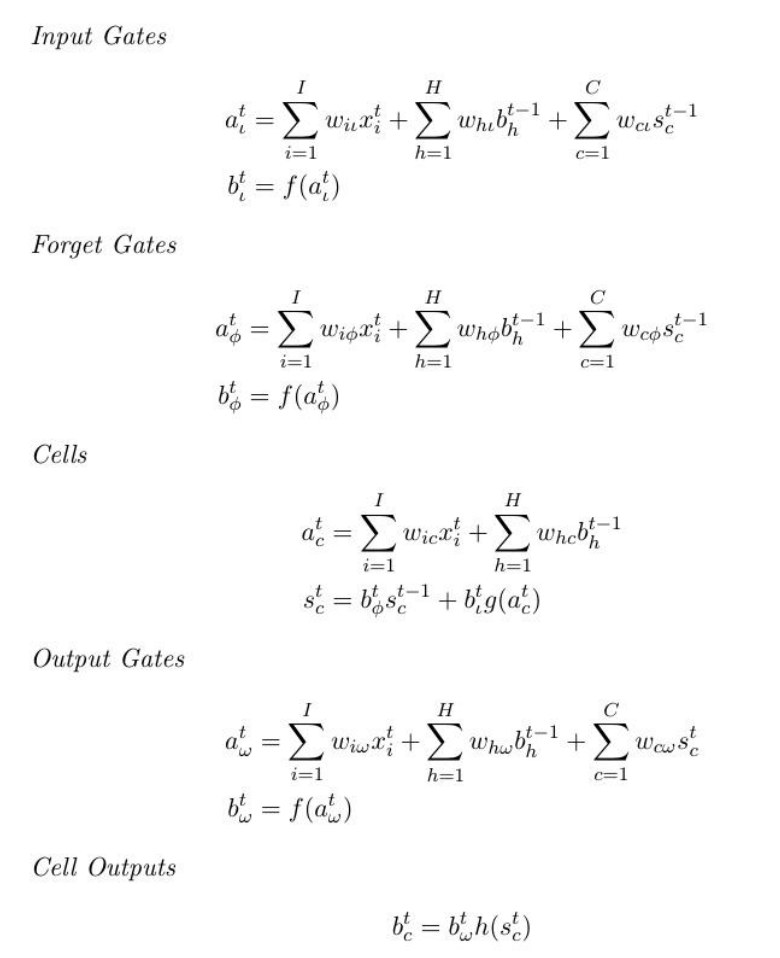

A GRU (Cho et al., 2014) is a cheaper cousin with two gates and no separate $c$. The point of both is the additive path. Once you have that, a vanilla RNN is a historical special case: no cell, no gates, $h_t$ is the memory and the output at once.
Go back to the one-unit toy. Replace the multiply-by-$0.5$ with a forget valve $f=1$. Then $c_t = c_{t-1} + i_t g_t$, and the first $1$ is still sitting in the cell at step $400$, plus whatever was written since. That is a different machine.
Bidirectional, and a door
A bidirectional RNN is two sticky notes, one running left to right and one right to left, concatenated at each $t$. Each position then sees both its past and its future. That helps tagging (“bank” as river or money: the next three words will tell you). It is cheating for causal language modelling, where the future is what you are trying not to look at.
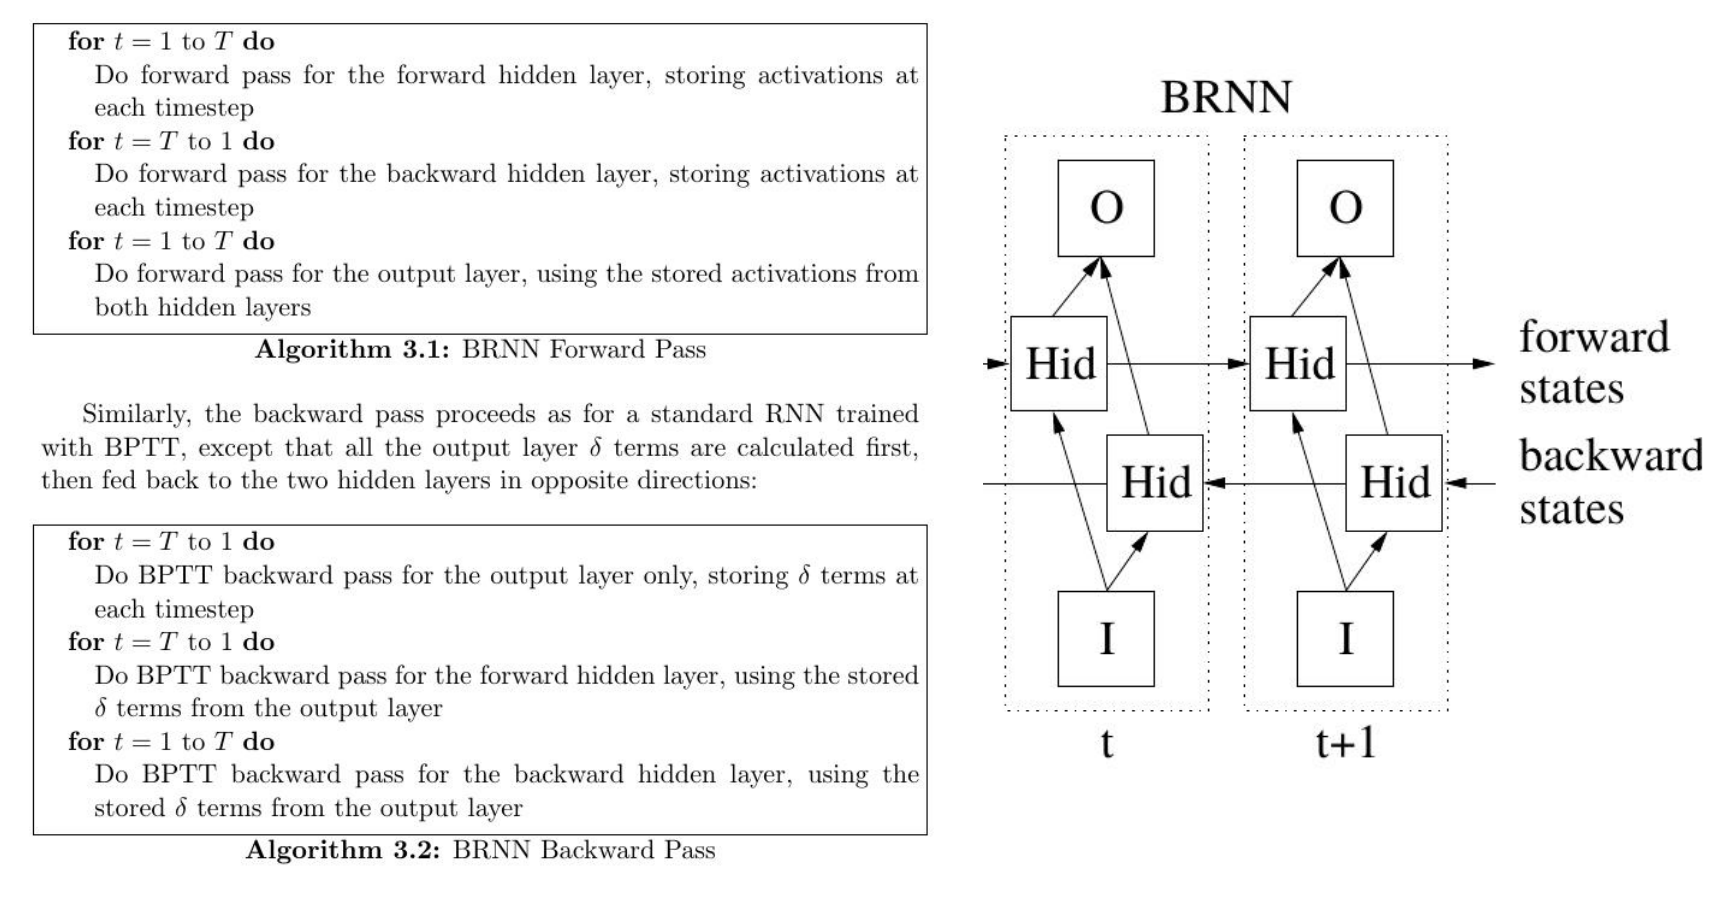
The door. Even with an LSTM, the path from $x_1$ to $y_T$ is a chain of $T$ steps. Training is sequential: you cannot compute $h_t$ before $h_{t-1}$. Attention, a later note in this series, throws the chain away. Every position looks at every other position in one matrix multiply, and a sentence of length $n$ is no longer a network of depth $n$. The sticky note was the right idea for 1997. The complete graph is the right idea for 2017.
A vanilla example in Python
Andrej Karpathy’s min-char-rnn.py is a hundred lines that are this note: one-hot characters, a vanilla hidden state, BPTT on a truncated window, sampling. The vanishing and exploding happen on lines 48–58 of the gist, where the backward loop multiplies into $W_{hh}$ at every step. Read it once.
- Gist: karpathy/d4dee566867f8291f086
- The essay that goes with it: The Unreasonable Effectiveness of Recurrent Neural Networks
What the napkin has claimed: a shared block, unrolled in time, trained by the chain rule, doomed by a product of Jacobians, repaired by an additive cell. The LSTM is the last great recurrent machine. It is also, for a first course in sequences, still the right one to compute by hand.
Cheers.
Further reading
Sepp Hochreiter and Jürgen Schmidhuber, Long Short-Term Memory. Neural Computation 9 (1997). The paper.
Andrej Karpathy, The Unreasonable Effectiveness of Recurrent Neural Networks. 2015. The character-level experiment.
Andrej Karpathy, Justin Johnson, and Li Fei-Fei, Visualizing and Understanding Recurrent Networks. ICLR workshop, 2016.
Yoshua Bengio, Patrice Simard, and Paolo Frasconi, Learning Long-Term Dependencies with Gradient Descent is Difficult. IEEE Trans. Neural Networks 5 (1994).
Rafal Jozefowicz, Wojciech Zaremba, and Ilya Sutskever, An Empirical Exploration of Recurrent Network Architectures. ICML 2015. Initialize the forget bias to $1$.
Alex Graves, Supervised Sequence Labelling with Recurrent Neural Networks. The coordinate-wise LSTM equations in the figures.